How to Connect a CMS, TMS, and ESP Without Losing Control of Localized Content
Enterprise brands rarely struggle to translate content. They struggle to move it cleanly between the systems that create, translate, and deliver it, without duplicating effort, losing approvals, or publishing stale locale variants. A content management system (CMS), translation management system (TMS), and email...
Enterprise brands rarely struggle to translate content. They struggle to move it cleanly between the systems that create, translate, and deliver it, without duplicating effort, losing approvals, or publishing stale locale variants. A content management system (CMS), translation management system (TMS), and email service provider (ESP) each assume they are the center of the content universe, and that tension is where localized content breaks down.
This guide gives architects a practical workflow for connecting these three systems while preserving a single source of truth. It defines system-of-record boundaries, explains how content IDs and locale metadata should travel across handoffs, and compares integration patterns so you can choose the right one for your stack. Throughout, we highlight where Ollang fits as the AI-powered execution layer that coordinates routing and delivery across video, audio, documents, and web content at enterprise scale.
Why the CMS → TMS → ESP Pipeline Breaks
Overlapping system-of-record assumptions
Every system in the pipeline believes it owns the content. Your CMS treats itself as the canonical store for web pages and marketing assets. Your TMS assumes it is the authority on all translated strings. Your ESP maintains its own template library with embedded copy. When each platform independently versions the same content, you end up with three competing records of what the "approved" French-Canadian email header actually says.
This overlap creates ghost content, locale variants that exist in one system but are outdated or absent in another. A marketing team updates a product description in the CMS, but the TMS still holds the previously approved translation, and the ESP is serving an even older version it cached during the last campaign build. Nobody is wrong according to their own system; the pipeline itself lacks a single arbitration point.
Manual handoffs that erode version integrity
The most common integration between these systems is not an API call, it is a person downloading a file, renaming it, and uploading it somewhere else. According to CSA Research, organizations that rely on manual file transfers for localization report significantly higher rates of rework and missed market deadlines compared to those with automated connectors.
Each manual handoff introduces risk: a translator works from a stale source file, a reviewer approves content that has already been superseded, or an engineer pastes a translation into the wrong template slot. Version integrity depends on every person in the chain doing the right thing at the right time, which is a fragile contract at any scale.
Content-ID and metadata mismatches across tools
A CMS might identify a content block as hero-banner-summer-2025. The TMS ingests it and assigns its own internal segment ID. The ESP references it by campaign name and variant letter. Without a shared content-ID schema and consistent locale metadata (language, region, script, formality level), there is no reliable way to trace a published string back to its approved translation or its original source.
These mismatches compound when you add markets. A single product launch across twelve locales can generate hundreds of content fragments, each needing a traceable path from authoring through approval to delivery. When IDs diverge, reconciliation becomes archaeological work.
Defining System-of-Record Boundaries
Source content: where the canonical version lives
The CMS should be the system of record for source-language content. This means every piece of copy, web page, landing page module, email body block, has a single canonical version in the CMS that is marked as approved before it enters the translation pipeline. No translation should begin from a draft, a Slack message, or a Google Doc side channel.
Practically, this requires two things: a clear "ready for localization" status in your CMS workflow, and a content-ID convention that persists across systems. A useful pattern is to assign a composite key like {content-type}.{slug}.{version} at the CMS level and require all downstream systems to reference it.
Translated assets: linguistic system of record vs. delivery copy
This is where existing guidance often contradicts itself. Some architects argue that approved translations should live in the TMS; others insist they belong in the CMS alongside the source. Both are partially right because they are describing different things.
The canonical linguistic asset is the approved translation as validated by a linguist or in-market reviewer. It belongs in the TMS (or a connected translation memory), where it can be leveraged for future projects, maintain terminology consistency, and serve as the audit trail for what was approved and when.
The published locale variant is the version of that translation formatted, personalized, and deployed in a delivery system, your CMS for web pages, your ESP for emails. This copy may include platform-specific placeholders, dynamic tokens, or layout adaptations that differ from the pure linguistic asset.
Confusing these two creates a governance problem. If you treat the ESP's copy as the linguistic record, you lose the ability to reuse translations across channels. If you treat the TMS as the delivery system, you introduce latency and lose platform-specific formatting.
Delivery channels: ESP templates, CMS locales, and beyond
Each delivery channel owns the presentation of localized content, not the content itself. The ESP owns email template structure, send logic, and personalization tokens. The CMS owns page layout, URL structure, and locale routing. Neither should be the place where translation decisions are made or linguistic quality is adjudicated.
This boundary matters operationally. When a marketer needs to update a single word in a French email subject line, the change should flow back through the TMS for approval and translation memory update, not be edited directly in the ESP, where it becomes an orphaned variant invisible to the rest of the pipeline.
The Workflow: Source Approval Through Market Delivery
Step 1, Author and approve source content in the CMS
Content authors create and finalize copy in the CMS. The editorial team reviews and marks the content as "approved for localization," which triggers a status change and, ideally, an event or webhook. At this point, the content-ID, version number, and target locales are locked.
Step 2, Extract, segment, and route to the TMS
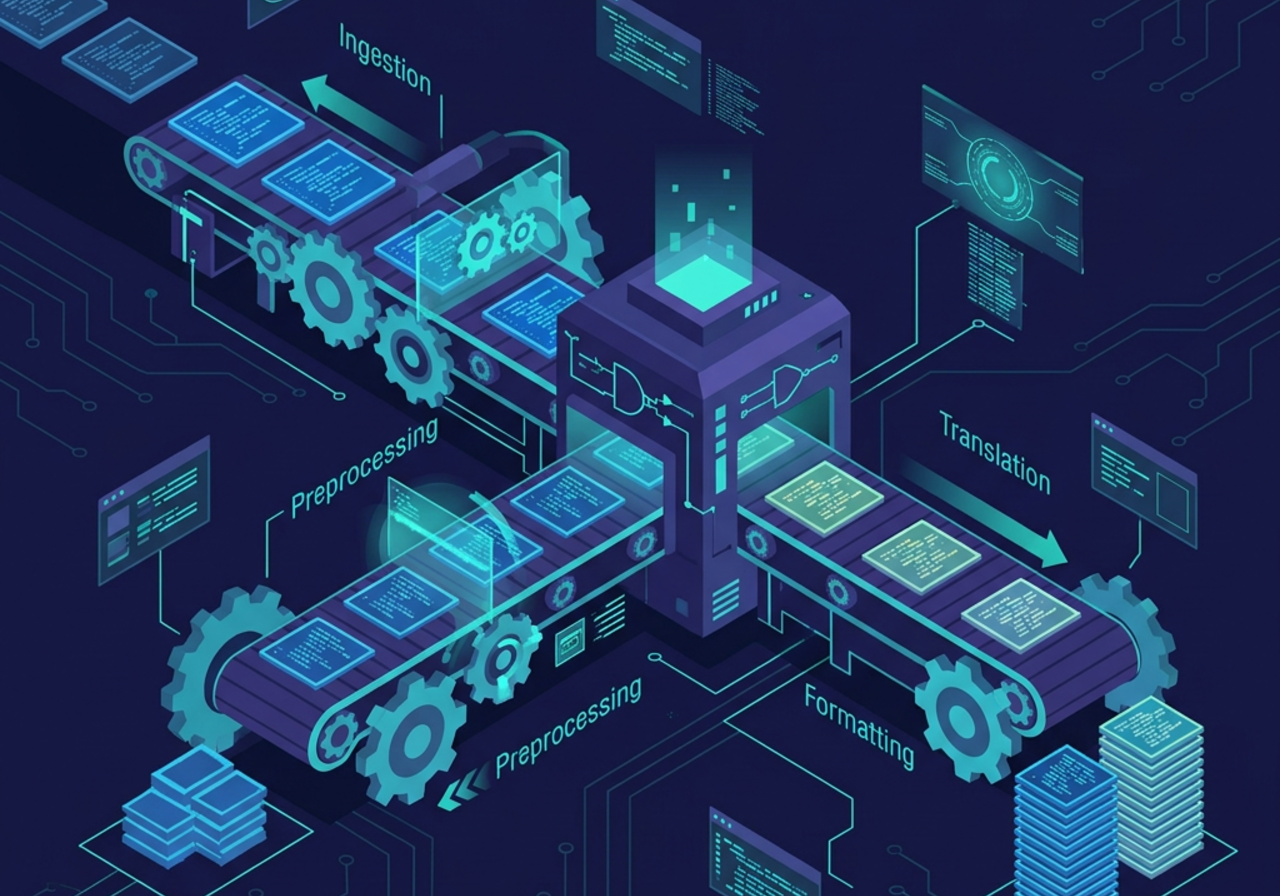
The approved content is extracted from the CMS, either via API connector or file export, and ingested by the TMS. During ingestion, the TMS segments the content into translatable units, applies translation memory matches, and routes segments to the appropriate workflow: machine translation, human translation, or a hybrid.
Key metadata must travel with the content: source locale, target locales, content-ID, version, deadline, and any placeholder or variable markup. Placeholders (e.g., {{first_name}}, {product_price}) should be protected as non-translatable tokens so translators do not accidentally modify dynamic insertion points.
Step 3, Translate, review, and lock linguistic assets
Translation and review happen inside the TMS. In-market reviewers validate tone, terminology, and cultural fit. Once approved, the translated segments are locked and stored in translation memory. The TMS should record the approval timestamp, reviewer identity, and the source-content version the translation was produced against.
This is the point where the canonical linguistic asset is established. It is immutable until a new source version triggers a retranslation cycle.
Step 4, Push locale-ready content to CMS and ESP
Approved translations are pushed back to the CMS for web publishing and to the ESP for email campaigns. During this handoff, platform-specific formatting is applied: the CMS wraps translations in the correct page templates and locale URL paths; the ESP inserts them into campaign templates with personalization tokens intact.
Each delivery system should record which TMS translation version it is currently serving, creating a traceable link from published content back to the approved linguistic asset.
Step 5, Validate, publish, and monitor
Before going live, automated checks should verify that all placeholders rendered correctly, no untranslated strings leaked through, and locale metadata (hreflang tags for web, language headers for email) is accurate. Post-publish monitoring should flag content drift, cases where a delivery system's copy no longer matches the latest approved translation in the TMS.
Ready to see Ollang in action?
Talk to our team about your localization goals and see how the Ollang platform fits your workflow.
Integration Patterns Compared
Choosing how to connect these systems is an architectural decision with long-term consequences. Three dominant patterns exist, each with distinct trade-offs.
CMS-first: the CMS as hub
In this pattern, the CMS orchestrates the entire flow. It sends content to the TMS, receives translations back, and pushes locale variants to the ESP. The CMS holds both source and translated content, and downstream systems pull from it.
Strengths: Simple mental model; one place to see all content. Works well when the CMS has robust localization features and strong API connectors.
Weaknesses: Most CMSs were not designed to be integration hubs. Connector quality varies wildly. The CMS becomes a bottleneck when you add channels beyond web (mobile apps, video subtitles, product feeds), and it rarely handles non-text content types like audio or video.
TMS-first: the TMS as hub
Here, the TMS sits at the center. It pulls source content from the CMS, manages translation, and pushes results to both the CMS and ESP. The TMS acts as the routing engine for all localized content.
Strengths: Translation memory and terminology are always in the loop. Linguistic governance is strong. Well-suited for organizations with a mature localization function.
Weaknesses: TMS platforms are optimized for translation workflows, not content delivery orchestration. Pushing formatted content to multiple endpoints often requires custom development. TMS connectors to ESPs are less mature than CMS connectors and, compared to orchestration platforms like Ollang, often require more bespoke integration work.
Orchestration-layer pattern: a dedicated coordination tier
An orchestration layer sits between all three systems, managing content routing, version synchronization, and delivery without replacing any existing tool. It receives approved source content from the CMS, routes it to the TMS, collects approved translations, and distributes locale-ready content to every delivery endpoint, CMS, ESP, mobile, video platforms, and more.
Strengths: Each system does what it does best. The orchestration layer handles the integration complexity, content-ID mapping, and version tracking that no single tool was designed to own. It scales naturally as you add new content types and delivery channels.
Weaknesses: Adds a layer to the stack. Requires clear governance around what the orchestration layer controls versus what individual systems control.
| Criteria | CMS-First | TMS-First | Orchestration Layer |
|---|---|---|---|
| Best for | Web-centric brands, few locales | Mature localization teams | Multi-channel, high-volume enterprises |
| Content types supported | Primarily text/web | Text, some file formats | Text, video, audio, documents, web |
| Connector complexity | Moderate | High (custom ESP work) | Managed by the layer |
| Linguistic governance | Weak | Strong | Strong (delegates to TMS) |
| Scalability across channels | Limited | Moderate | High |
For most enterprise brands operating across web, email, video, and document channels, the orchestration-layer pattern offers the most sustainable architecture. It avoids forcing a CMS or TMS into a role it was not built for while preserving each system's strengths. Platforms such as Ollang implement this pattern to coordinate multi-format localization at scale.
Where Ollang Fits as the Execution Layer
When your integration challenge is not about finding another translation vendor but about coordinating the movement of localized content across systems, formats, and channels, that is where Ollang operates.
Coordinating routing across video, audio, documents, and web
Ollang functions as the AI-powered execution layer that sits in the orchestration tier of your localization architecture. Rather than replacing your CMS, TMS, or ESP, Ollang connects to them and manages the routing, transformation, and delivery of localized content across every format your enterprise produces, web pages, email campaigns, product videos, training audio, PDFs, and support documentation. Ollang preserves content IDs, locale metadata, and placeholder integrity end to end, routing the right artifact to the right channel.
This matters because most integration failures happen at format boundaries. Your TMS handles website strings well but struggles with video subtitle timing. Your CMS publishes web content but has no concept of dubbed audio tracks. Ollang normalizes these workflows so that a single localization event, say, a product launch in eight markets, flows through one coordinated pipeline regardless of whether the output is a landing page, a launch video, a sales deck, or an onboarding email sequence.
Replacing manual handoffs with governed automation
Every manual handoff described earlier in this article, the file download, the rename, the re-upload, is a point where Ollang introduces governed automation. Content-IDs and locale metadata are preserved end to end. Version handoffs between systems are logged and traceable. Placeholder integrity is validated before delivery, not after a broken email reaches a customer's inbox. Ollang records every handoff and version change, creating an auditable trail without manual intervention.
For enterprise localization teams, this means fewer escalations, faster time to market, and an audit trail that satisfies both brand governance and regulatory requirements. The execution layer does not make linguistic decisions, it ensures that the decisions made by translators, reviewers, and content owners are faithfully carried through to every published touchpoint.
Practical Guardrails for Architects
Enforce a single content-ID schema
Agree on a content-ID convention before you build connectors. The ID should be human-readable, include the content type and version, and persist unchanged across CMS, TMS, ESP, and any orchestration layer. If your CMS generates IDs that your TMS cannot ingest, you will spend more time on reconciliation than translation.
Protect placeholders as non-translatable tokens
Define a placeholder syntax (e.g., double curly braces for personalization, single curly braces for system variables) and enforce it in your TMS configuration. Translators should see placeholders as locked, non-editable elements. Automated QA checks should flag any translation where a placeholder was modified, removed, or duplicated.
Separate linguistic approval from publication approval
These are two different decisions made by two different roles. Linguistic approval happens in the TMS and confirms that the translation is accurate, on-brand, and culturally appropriate. Publication approval happens in the CMS or ESP and confirms that the formatted, personalized content is ready to go live. Conflating them leads to either linguistic shortcuts or publication delays.
Version-lock translations to source versions
Every translation should be linked to a specific source-content version. When the source changes, the translation should be flagged for review, not silently served alongside updated source content. This prevents the common scenario where a legal disclaimer is updated in English but the German translation still reflects the previous version.
Ready to see Ollang in action?
Talk to our team about your localization goals and see how the Ollang platform fits your workflow.
Conclusion
Connecting a CMS, TMS, and ESP without losing control of localized content is fundamentally an architecture problem, not a translation problem. The solution lies in defining clear system-of-record boundaries, maintaining a single content-ID schema across tools, and choosing an integration pattern that matches your organization's scale and channel diversity.
For enterprise brands producing localized content across web, email, video, audio, and documents, the orchestration-layer pattern consistently outperforms CMS-first or TMS-first approaches because it lets each system focus on its core competency. Ollang serves as this execution layer, coordinating the routing, format transformation, and governed delivery of localized content across every channel without adding manual handoffs or displacing the tools your teams already rely on. The result is a pipeline where approved translations reach every market and every touchpoint intact, traceable, and on time.
Published on October 13, 2026