
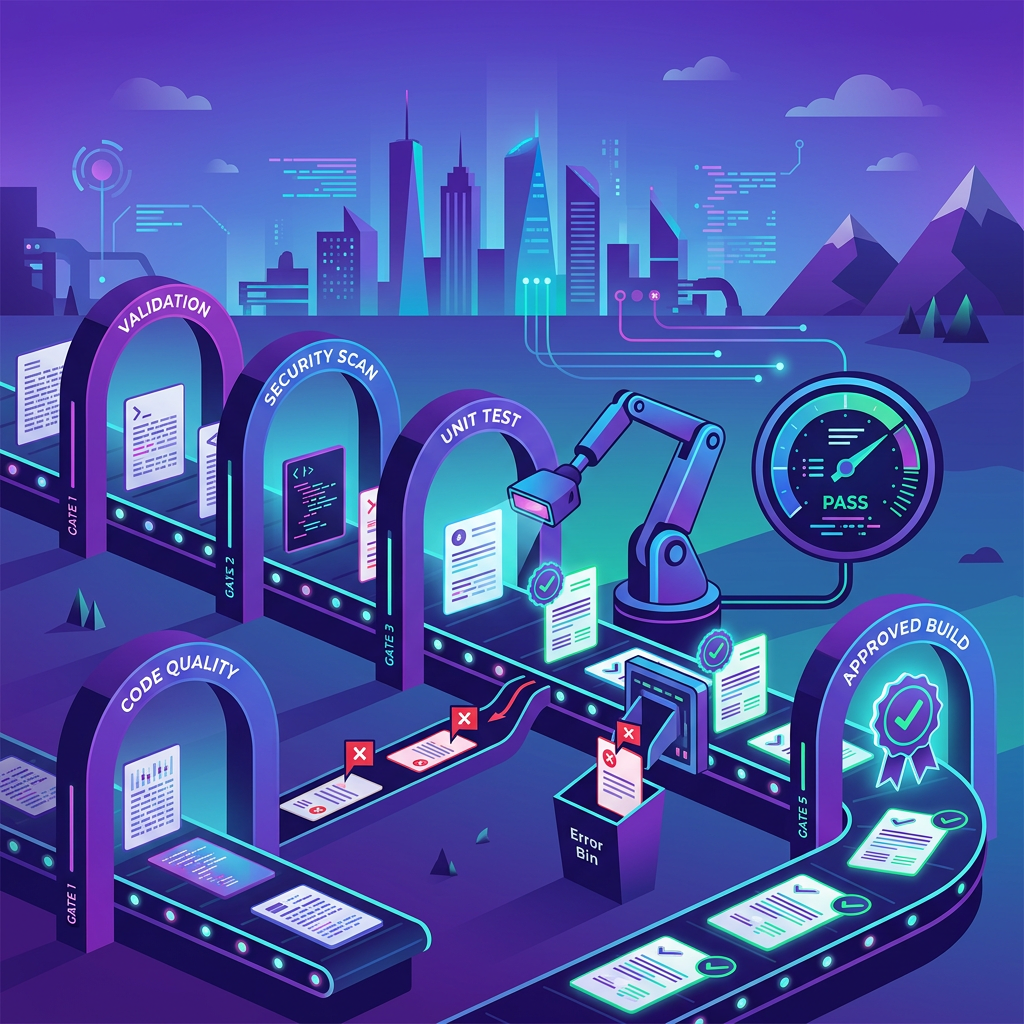
Most localization defects that reach production are preventable. They slip through not because teams lack skilled linguists, but because quality assurance is treated as a final hurdle rather than an engineered process. A missing placeholder crashes a mobile app. An untranslated legal clause exposes liability. A truncated button label erodes user trust in a new market. These failures share a common root: the absence of structured, repeatable QA with clearly defined error taxonomies, automated checks, and explicit release criteria.
This guide walks through the Multidimensional Quality Metrics (MQM) framework, automated validation layers, human review workflows, and the release quality gates that separate localization programs shipping with confidence from those shipping with crossed fingers. By the end, you will have a concrete blueprint for a defensible QA model.
What Is MQM and Why Does It Matter for Localization QA?
The Multidimensional Quality Metrics framework, referenced in standardization efforts such as the ASTM International work item WK54884, provides a hierarchical error typology purpose-built for translation quality evaluation. Rather than relying on vague judgments like "this translation feels off," MQM gives evaluators a shared vocabulary and a scoring mechanism that produces comparable, actionable results across languages, vendors, and content types.
MQM Error Typology Explained
MQM organizes translation errors into a tree of categories and subcategories. The top-level dimensions include:
| MQM Dimension | What It Captures | Example Errors |
|---|---|---|
| Accuracy | Whether meaning is faithfully transferred | Mistranslation, omission, addition, untranslated text |
| Fluency | Whether the target text reads naturally | Grammar, spelling, punctuation, register |
| Terminology | Whether approved terms are used consistently | Wrong term, inconsistent term use |
| Style | Whether the text matches style guide expectations | Awkward phrasing, tone mismatch |
| Locale Convention | Whether locale-specific formats are correct | Date, number, currency, address formats |
| Design | Whether the text fits its UI context | Truncation, text overlap, character encoding |
Each error is assigned a severity level, typically critical, major, or minor, which feeds directly into scoring. A critical accuracy error (e.g., a dosage instruction mistranslated in a pharmaceutical label) carries far more weight than a minor fluency issue (e.g., a slightly awkward conjunction).
How MQM Scoring Works in Practice
MQM scoring converts annotated errors into a single quality score per language or per content segment. The most common formula applies penalty points by severity:
- Critical: 10 points per error (or higher, depending on the domain)
- Major: 5 points per error
- Minor: 1 point per error
The raw penalty total is then normalized against the word count of the evaluated sample to produce a score per thousand words. Organizations set pass/fail thresholds based on content type, marketing copy might tolerate a higher score than medical device instructions.
This scoring approach does two things traditional "percentage accuracy" methods cannot. First, it differentiates between a translation riddled with trivial typos and one containing a single catastrophic mistranslation. Second, it produces data that can be trended over time, compared across vendors, and used for contractual SLAs.
Setting Severity Weights and Pass/Fail Thresholds
The right thresholds depend on risk. A common starting framework:
| Content Type | Max Penalty per 1,000 Words | Typical Rationale |
|---|---|---|
| Legal / Regulatory | ≤ 2 | Compliance exposure; errors may have legal consequences |
| Medical / Life Sciences | ≤ 3 | Patient safety; governed by ISO 17100 and domain-specific standards |
| Software UI | ≤ 5 | User experience impact; functional errors may block workflows |
| Marketing / Web | ≤ 8 | Brand perception; more subjective, higher tolerance for style variance |
| Internal / Support KB | ≤ 12 | Lower external visibility; functional accuracy still required |
These numbers are not universal rules, they are calibration points. The critical step is documenting the thresholds, getting stakeholder agreement, and applying them consistently. Revisit them quarterly as your error data accumulates and patterns emerge.
How to Build an LQA Sampling Plan
Evaluating every translated word is neither practical nor cost-effective. Linguistic Quality Assurance (LQA) relies on statistical sampling to draw reliable conclusions about overall quality from a manageable review volume.
Statistical Sampling: How Many Segments to Review
The goal of sampling is confidence: you need enough data points to trust that the sample reflects the full delivery. A common baseline is reviewing 1,500-2,000 words per language per delivery, which aligns with the sample sizes historically recommended by localization industry bodies for achieving a reasonable confidence interval.
For high-risk content, increase the sample. For mature language pairs with a strong track record, you can reduce it. The key variables are:
- Total word count of the delivery
- Number of unique translators contributing
- Content risk level (regulatory vs. informational)
- Historical quality trends for the language pair
Stratified sampling, selecting segments proportionally from different content types, translators, or modules, gives a more representative picture than random sampling alone.
Stratified vs. Random Selection
Random sampling is simple but can miss systematic issues. If one translator handled all the legal content and another handled the UI strings, a purely random sample might over-represent one and under-represent the other.
Stratified sampling divides the corpus into meaningful strata (by translator, content type, module, or source complexity) and draws proportional samples from each. This ensures your evaluation covers the full risk surface. In practice, many teams use a hybrid: stratified selection for the bulk of the sample, with a random overlay to catch unexpected patterns.
Reviewer Calibration and Inter-Annotator Agreement
MQM scores are only meaningful if reviewers apply the typology consistently. Calibration sessions, where two or more reviewers independently evaluate the same set of segments, then compare and discuss their annotations, are essential before any evaluation cycle begins.
Measure inter-annotator agreement (IAA) using metrics like Cohen's kappa or percentage agreement on severity classification. An IAA below 0.6 typically signals that the error definitions or severity guidelines need clarification. Document disagreements and update your evaluation guidelines accordingly. This is not overhead; it is the foundation of trustworthy quality data.
Automated QA Checks Every Localization Team Needs
Automation handles the mechanical, pattern-based errors that humans should never have to waste time catching. A well-configured automated QA layer eliminates entire categories of defects before a human reviewer ever opens the file.
ICU Placeholder and Variable Validation
ICU MessageFormat patterns (e.g., {count, plural, one {# item} other {# items}}) are notoriously fragile. A missing brace, a renamed variable, or a dropped plural category will cause runtime crashes or display raw code to users. Automated validators parse both source and target, flag mismatched or missing placeholders, and verify that plural rules align with the Unicode CLDR plural categories for the target locale.
HTML, Markdown, and XML Tag Integrity
Translated content embedded in HTML, Markdown, or XML must preserve the tag structure of the source. Unclosed tags, reordered nesting, or deleted attributes break rendering. Automated checks compare the tag skeleton of source and target segments, flagging any structural divergence. This is especially critical for web and help center content where a single unclosed <strong> tag can cascade formatting errors across an entire page.
Terminology and Glossary Enforcement
Term consistency is both a brand concern and a functional one, using "cancel" in one screen and "abort" in another confuses users. Automated term checks compare translated segments against an approved termbase and flag deviations. The best implementations distinguish between mandatory terms (must be used as specified) and preferred terms (recommended but flexible), reducing false positives that erode translator trust in the tool.
String Length, Truncation, and UI Fit
German text averages 30% longer than English. Finnish compound words can stretch a single UI label beyond any reasonable button width. Automated length checks compare target character or pixel length against defined limits per string, flagging potential truncation before it reaches a build. For mobile apps, where screen real estate is tightly constrained, this check alone prevents a significant share of visual defects.
Bidirectional (Bidi) and RTL Control Characters
Arabic, Hebrew, and other right-to-left scripts require correct use of Unicode bidirectional control characters (LRM, RLM, LRE, RLE, PDF, and the isolate equivalents). Misplaced or missing bidi marks cause numbers, punctuation, and mixed-direction text to render in the wrong order. Automated checks verify that bidi controls are present where expected and absent where they would cause harm, particularly in strings that mix RTL text with LTR elements like URLs, file paths, or brand names.
Spellcheck, Banned Terms, and Locale-Specific Linting
Spellcheck is table stakes, but locale-specific linting goes further. It verifies that date formats match the target locale (DD/MM/YYYY vs. MM/DD/YYYY), that currency symbols are correct, that measurement units are converted where required, and that culturally inappropriate or legally banned terms are flagged. Banned term lists are especially important for regulated industries where specific claims or phrases are prohibited in certain markets.